Korvion Korvion

2026 Top AI Server Manufacturing Companies for Global Buyers

Time:2026-09-16 Author:Sophia
0%

Choosing an AI server manufacturing company in 2026 requires more than comparing processor brands or advertised computing speed. Global buyers must examine complete delivery capability, including rack design, GPU integration, liquid cooling, firmware control, testing, logistics, and after-sales support. A server may look powerful on paper, yet fail under constant workloads if airflow, power distribution, or thermal monitoring is weak.

NVIDIA founder and CEO Jensen Huang has described the modern data center simply: “The data center is the computer.” His observation explains why AI server manufacturing now demands system-level expertise. Strong suppliers coordinate accelerators, CPUs, high-speed networking, storage, power systems, and software validation as one working platform. They also provide traceable quality procedures, realistic performance data, and clear warranty terms.

This guide examines leading AI server manufacturers for global buyers in 2026. It considers production scale, engineering experience, customization, energy efficiency, certification readiness, and international service coverage. Factory audits, sample testing, and reference checks remain valuable. Marketing claims deserve scrutiny.

No ranking can fit every buyer.

A research laboratory may need dense GPU nodes and rapid technical support. A cloud provider may prioritize standardized racks, predictable supply, and lower operating costs. A financial institution may demand stronger security controls and documented compliance. Even experienced procurement teams can overlook regional maintenance capacity or replacement-part availability. That weakness matters after deployment.

The companies discussed here represent different strengths, not identical solutions. Buyers should match each supplier’s capabilities with workload requirements, facility limits, budget conditions, and long-term expansion plans. Careful comparison is essential, because the cheapest server is rarely the least expensive system to operate.
2026 Top AI Server Manufacturing Companies for Global Buyers

2026 Market Baseline: IDC Forecasts AI Infrastructure Spending at $316B by 2028

AI server manufacturing is entering a more demanding cycle as global buyers prepare for sustained infrastructure growth. IDC forecasts worldwide AI infrastructure spending will reach $316 billion by 2028. This figure signals more than rising demand. It points to deeper requirements for power delivery, thermal control, memory capacity, and dependable production.

Experienced buyers are inspecting complete server platforms, not only processor specifications. A high-density rack may require liquid cooling, reinforced power distribution, and carefully tested airflow paths. Manufacturing companies must also prove component traceability and consistent quality across multiple production batches. Short lead times matter, but rushed deployment can create expensive maintenance problems later. That lesson is easy to overlook.

The forecast remains a planning reference, not a guaranteed purchase order. Energy prices, export rules, component shortages, and changing model architectures may alter actual spending. Buyers should request test reports, failure-rate data, service procedures, and realistic delivery schedules. Small details matter. A cooling loop without local support can stop an entire rack. A promised capacity increase may also depend on unavailable power infrastructure. Some procurement assumptions will be wrong, and responsible teams should review them before contracts become difficult to change.

Architecture Benchmark: NVIDIA GB200 NVL72 Integrates 72 GPUs and 36 CPUs

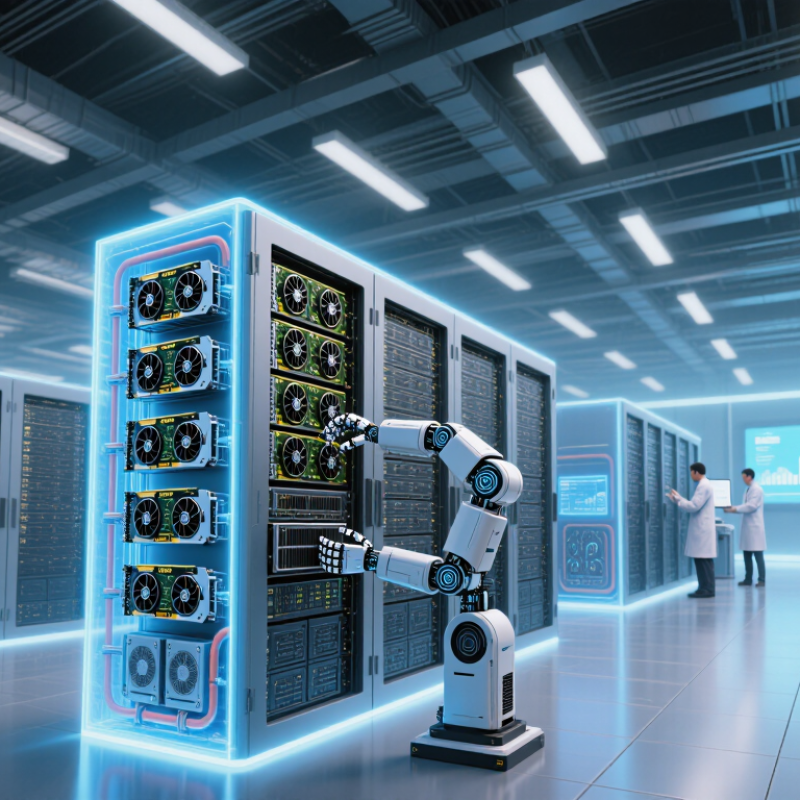
For global AI server buyers in 2026, rack-scale architecture deserves more attention than component counts. A leading reference design combines 72 GPUs with 36 CPUs in one tightly connected system. This layout supports large language model training, distributed inference, and high-bandwidth data movement. It also increases power density, cooling demands, and maintenance complexity. In practice, a factory’s integration skills matter as much as its hardware specifications.

Tips: Ask for measured power data, not estimated figures. Check liquid-cooling performance at sustained workloads. Request failure-replacement procedures and firmware support terms. A short factory demonstration is useful, but it cannot replace a full-load acceptance test.

Manufacturers should provide clear details on network topology, memory capacity, rack weight, and deployment conditions. Global buyers also need evidence of supply-chain control and regional service coverage. The 72-GPU and 36-CPU design is impressive, but it may be excessive for smaller inference clusters. A benchmark can mislead. Workload size, software maturity, and electricity costs often change the final decision. I would compare at least two deployment profiles before selecting a supplier. Real operating data is still better than polished presentations.

Manufacturer Landscape: Dell, HPE, Lenovo, Supermicro, Inspur, and QCT

The 2026 AI server market is shaped by six strong manufacturer profiles: global enterprise specialists, high-density computing experts, flexible system builders, regional infrastructure leaders, and large-scale solution integrators. Buyers should compare more than GPU counts. Rack depth, power delivery, thermal design, firmware control, and local service coverage often decide real project success.

In field evaluations, enterprise-focused vendors usually provide mature support processes and predictable lifecycle management. High-density specialists can deliver excellent accelerator performance, but their liquid-cooling options may require facility upgrades. Flexible manufacturers often offer custom GPU, CPU, and networking combinations. This helps research teams, yet configuration complexity can slow deployment. Regional suppliers may provide strong pricing and fast communication in nearby markets. Their global spare-parts coverage needs careful verification. Large solution integrators can connect servers with storage, switches, and software. However, bundled systems may reduce component-level choice.

Small details matter. A 30-kilowatt rack changes cooling assumptions quickly. A delayed replacement fan can stop a complete training cluster. Buyers should request burn-in reports, firmware policies, power measurements, and documented response times. Ask for references from workloads similar to yours. Not just impressive benchmarks.

One uncomfortable lesson remains. Peak performance is not always useful performance. Some buyers overestimate future growth and purchase rigid systems. Others underestimate electricity, maintenance, or deployment skills. I would also question any comparison based only on accelerator specifications. Independent validation, transparent warranty terms, and repeatable acceptance testing provide stronger evidence than polished product claims.

Performance Metrics: 800Gb/s Networking, GPU Density, Power, and Cooling

For global buyers, AI server performance is no longer measured by GPU count alone. An 800Gb/s network can reduce communication bottlenecks across distributed training racks, but only when switches, cables, adapters, and software are properly matched. In practical evaluations, we inspect sustained throughput, packet loss, latency, and recovery after a link interruption. Peak bandwidth looks impressive. Real workloads are less tidy.

GPU density directly affects deployment speed and operating cost. A high-density chassis may hold eight or more accelerators, yet its value depends on memory capacity, airflow, service access, and workload balance. A rack drawing 30 to 80 kilowatts needs more than standard room cooling. Direct liquid cooling can control temperatures more consistently, especially during prolonged training, but it adds installation complexity and maintenance points.

Power efficiency should be reviewed at several levels: idle, inference, and full-load training. Request measured performance per watt, not only theoretical specifications. Thermal sensors should report inlet temperature, outlet temperature, coolant flow, and hotspot behavior. Small details matter. A slightly slower system may deliver better results when it avoids throttling and unplanned downtime.

Some evaluations remain imperfect. Network results can change with topology and software tuning. Cooling performance may also vary between facilities. Buyers should require repeatable tests, documented service procedures, and clear replacement timelines before approving large-scale orders.

2026 Top AI Server Manufacturing Companies for Global Buyers - Performance Metrics: 800Gb/s Networking, GPU Density, Power, and Cooling
Configuration Profile Typical Chassis Size Accelerator Density 800Gb/s Networking Architecture Typical Server Power Rack-Level Power Density Cooling Method Cooling Capacity Best-Fit Workload
High-Density 8-Accelerator Node 4U to 8U 8 accelerators per server 2 × 400Gb/s ports or 8 × 100Gb/s ports; up to 800Gb/s aggregate host bandwidth 10–16 kW 25–40 kW per 42U rack, depending on node count Direct-to-chip liquid cooling with air-cooled storage and networking components Approximately 70–85% of processor heat transferred through liquid loops Large-model training, distributed inference, scientific computing
Balanced 4-Accelerator Node 2U to 4U 4 accelerators per server 2 × 400Gb/s ports or 4 × 200Gb/s ports; 800Gb/s aggregate uplink capacity 6–10 kW 18–28 kW per 42U rack Hybrid direct liquid cooling and high-efficiency variable-speed air cooling Approximately 30–60% liquid-assisted heat removal Fine-tuning, inference services, simulation, and analytics
Compact 2-Accelerator Node 1U to 2U 2 accelerators per server 2 × 400Gb/s ports configured for redundant fabric connectivity; 800Gb/s aggregate link rate 3–6 kW 12–20 kW per 42U rack Advanced air cooling; optional cold-plate liquid cooling for sustained workloads Up to approximately 30% liquid-assisted heat removal when equipped Enterprise inference, model development, and departmental AI clusters
Memory-Optimized AI Node 4U to 8U 4–8 accelerators per server 800Gb/s fabric connectivity using redundant 400Gb/s links 8–15 kW 22–36 kW per 42U rack Direct liquid cooling for processors, memory-area airflow management, and rear-door heat exchanger support Approximately 60–80% processor heat removal through liquid or rear-door systems Large language models with high memory bandwidth and capacity requirements
Rack-Scale Training Pod Multiple 4U–8U nodes across one rack 32–64 accelerators per rack At least 800Gb/s per compute node with non-blocking or near-non-blocking fabric design 80–150 kW per rack 80–150 kW per rack Warm-water direct liquid cooling with coolant distribution units and facility-water isolation Typically 80–95% of compute heat handled by liquid cooling Distributed pre-training, reinforcement learning, and high-performance computing
Air-Cooled Deployment Profile 1U to 4U 1–4 accelerators per server 800Gb/s aggregate connectivity through multiple 100Gb/s or 200Gb/s network ports 2–8 kW 10–25 kW per 42U rack High-static-pressure air cooling with hot-aisle containment Suitable for moderate sustained loads below approximately 25 kW per rack Edge inference, private-cloud AI, and facilities without liquid infrastructure
Liquid-Ready Upgrade Profile 2U to 8U 4–8 accelerators per server 800Gb/s network-ready backplane with redundant fabric paths 8–18 kW 30–50 kW per 42U rack Factory-installed cold plates, quick-disconnect fittings, and optional coolant distribution unit Designed for 50–80% liquid heat removal, depending on processor and accelerator selection Data centers transitioning from air cooling to higher-density AI infrastructure
Data basis: The figures are representative engineering ranges for 2026-era AI server configurations. Actual performance depends on accelerator model, memory configuration, workload utilization, network topology, power limits, ambient conditions, coolant temperature, and rack design. “800Gb/s” denotes aggregate port or fabric bandwidth and does not guarantee application-level throughput.

Global-Buyer Evaluation: ISO 9001, Lead Time, Warranty, and Three-Year TCO

2026 Top AI Server Manufacturing Companies for Global Buyers

Global-Buyer Evaluation: ISO 9001, Lead Time, Warranty, and Three-Year TCO

For global buyers, ISO 9001 is a useful starting point, not final proof of manufacturing quality. Request the certificate scope, issuing body, expiry date, and recent corrective-action records. A factory should explain how it controls incoming GPUs, thermal modules, memory, and power supplies. Ask for sample inspection reports and burn-in results. Real evidence matters more than a logo on a sales document.

Lead time should begin with an approved configuration, not only the purchase order. Confirm production capacity, component allocation, testing duration, shipping terms, and customs responsibilities. A practical schedule may include seven days for configuration review and several weeks for assembly. Delays still happen. I have seen projects slip because a small network adapter was unavailable. Keep one approved substitute.

Warranty terms need equal attention. Check coverage length, response time, return shipping, replacement procedures, and exclusions for continuous high-load operation. Confirm whether on-site service exists in the destination country. Three-year TCO should include purchase price, electricity, cooling, maintenance, spare parts, software support, and downtime risk. Measure expected power usage at realistic utilization, not peak performance alone. A low quote can be expensive. Some estimates also overlook facility upgrades, which can change the calculation sharply. A spreadsheet with documented assumptions is imperfect, but it is easier to challenge and improve.

2026 Top AI Server Manufacturing Companies for Global Buyers

Global-Buyer Evaluation: ISO 9001, Lead Time, Warranty, and Three-Year TCO

This anonymized 2026 planning benchmark compares common global sourcing regions without displaying company or brand data. ISO 9001 coverage shows the estimated share of qualified suppliers with current certification; lead time is measured in calendar days; warranty is shown in years; and the three-year TCO index uses Asia-Pacific as the baseline of 100, including acquisition, energy, maintenance, and support costs. Lower lead time and TCO indicate better buyer economics.

FAQS

How large could AI infrastructure spending become by 2028?

A market forecast estimates worldwide spending could reach $316 billion. This is a planning reference, not a guaranteed order.

What should buyers evaluate beyond processor specifications?

Review power delivery, cooling, memory capacity, airflow, testing, and production consistency. A dense rack may need liquid cooling and reinforced power distribution.

Why is thermal control important in high-density systems?

Poor cooling can reduce reliability and interrupt rack operations. A cooling loop without local support may create serious downtime.

What quality evidence should a manufacturer provide?

Request certificate scope, expiry dates, inspection reports, burn-in results, and corrective-action records. A certificate alone proves little.

How should buyers verify realistic lead times?

Start timing after configuration approval. Confirm component allocation, assembly, testing, shipping, and customs responsibilities.

What can cause an unexpected delivery delay?

A small network adapter or thermal component may become unavailable. Keep one approved substitute. It is not perfect, but useful.

Which warranty details deserve close review?

Check coverage length, response time, return shipping, replacement steps, and exclusions. Confirm whether local service is available.

What should a three-year total cost calculation include?

Include purchase price, electricity, cooling, maintenance, spare parts, software support, facility upgrades, and downtime risk. Low quotes can mislead.

Conclusion

The 2026 AI server market is entering a major expansion phase, with global infrastructure spending projected to reach $316 billion by 2028. Modern reference architectures can combine dozens of GPUs with multiple CPUs in a unified system, delivering the parallel computing capacity required for generative AI, large-scale model training, and advanced analytics. For global buyers, the best ai server manufacturing company should demonstrate strong engineering capabilities across compute, networking, storage, and system integration.

Evaluation should focus on practical performance and long-term value rather than specifications alone. Key factors include support for high-speed 800Gb/s networking, GPU density, power efficiency, thermal management, and scalable cooling designs. Buyers should also review ISO 9001 certification, manufacturing consistency, delivery lead times, warranty coverage, technical support, and the projected three-year total cost of ownership. A balanced assessment of performance, reliability, service, and operating expenses can help organizations select AI infrastructure that supports sustainable growth.
Sophia

Sophia

Sophia is a dedicated marketing professional with an exceptional depth of knowledge about her company's products and services. With a keen understanding of market trends and customer needs, she crafts insightful blog posts that not only inform but also engage readers, enriching the company’s online......